You ask an AI a simple question about a recent legal ruling or a specific medical dosage. It answers confidently. The grammar is perfect. The tone is helpful. But the facts are wrong. This isn't a rare glitch; it's a structural feature of how Large Language Models predict the next token based on statistical probability rather than truth. Studies using benchmarks like HaluEval show that even top-tier models like GPT-4 produce factual errors in 15-25% of responses across diverse domains. For hobbyists, this is annoying. For developers building healthcare or financial apps, it’s a liability.
The solution isn't just to hope the model gets smarter. It’s to build a safety net while the text is being generated. We call this online verification. Unlike post-hoc checking, where you review the output after the fact, online verification intercepts claims as they emerge, checks them against reliable sources, and corrects them in real-time. This approach can reduce factual errors by 40-60%, according to experiments with frameworks like OpenFactCheck. But how do you actually implement this without turning your chatbot into a slow, expensive mess? Let’s break down the mechanics, the tools, and the pitfalls.
The Three-Stage Pipeline: How Online Verification Works
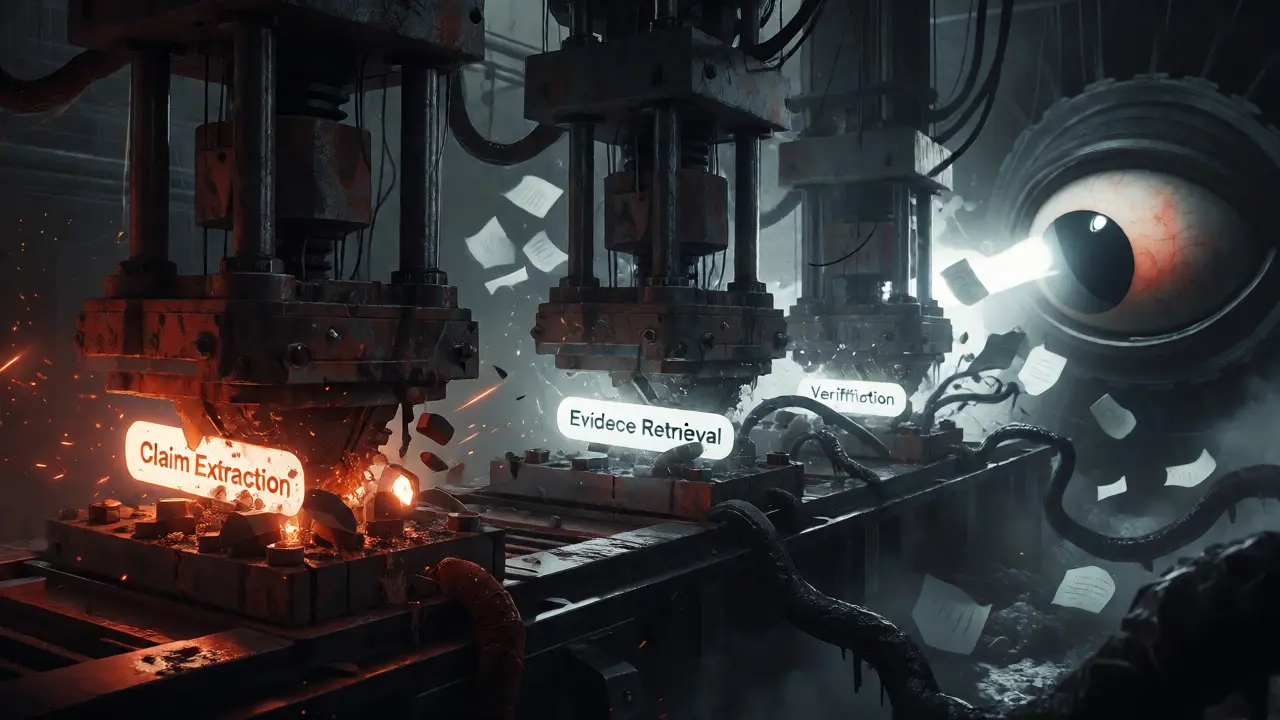
Most robust verification systems don’t just "check" the whole paragraph at once. That’s too vague. Instead, they follow a strict three-stage pipeline: claim extraction, evidence retrieval, and verification. Think of it as a digital assembly line for truth.
First, the system performs Claim Extraction. It decomposes the generated text into atomic, context-independent statements. If the model says, "Paris is the capital of France and has a population of 2 million," the extractor splits this into two distinct claims. State-of-the-art systems like FactScore achieve over 87% precision in this segmentation step. Why does this matter? Because if you verify the whole sentence, one error might mask another, or a correct part might validate an incorrect part. Atomic claims isolate the risk.
Next comes Evidence Retrieval. The system searches authoritative sources-Wikipedia, verified news databases, or your company’s internal knowledge base-for information supporting or refuting each claim. Modern implementations use a hybrid approach, combining BM25 keyword search with dense vector retrieval. This combo boosts evidence recall to nearly 93% on standard benchmarks like FEVER. Without good retrieval, you’re verifying against noise.
Finally, the Verification Phase decides if the claim is true, false, or unverifiable. This often uses Natural Language Inference (NLI) models or an "LLM-as-judge" setup. A verifier model reads the claim and the retrieved evidence and outputs a confidence score. If the score is low, the system flags the claim or rewrites it. This loop happens during generation, allowing the model to self-correct before the user sees the final answer.
Comparing the Heavyweights: OpenFactCheck vs. FactScore vs. Noblis G3
Not all verification strategies are created equal. Your choice depends on whether you prioritize speed, accuracy, or customization. Here’s how the leading frameworks stack up in 2026.
| Framework | Accuracy (Avg) | Latency per Claim | Cost Efficiency | Best Use Case |
|---|---|---|---|---|
| OpenFactCheck | 81.7% | High (47 min/doc) | Moderate | R&D, Complex Custom Pipelines |
| FactScore | 76.8% | Low (2.3 sec) | High | Production Apps, Speed-Critical |
| Noblis G3 | 85.2% | Moderate | Low (High Setup Cost) | Enterprise/Govt Technical Docs |
| Perplexity.ai | 72.1% | Very Low (1.8 sec) | Variable | Consumer Search, Quick Answers |
OpenFactCheck, released by Stanford researchers in early 2024, is the Swiss Army knife. It integrates multiple modules like CustChecker and LLMEval, offering high accuracy (81.7%) but at a computational cost. Full evaluation can take nearly an hour per document on standard hardware. It’s ideal for research teams who need to tweak every parameter of the verification process.
In contrast, FactScore, developed by Carnegie Mellon, prioritizes efficiency. It processes claims 3.2x faster than OpenFactCheck but sacrifices some accuracy (76.8%). For a customer support bot that needs to respond in under five seconds, FactScore is the pragmatic choice. Developers praise its simplicity but note that adapting it to niche domains like medicine requires significant NLP expertise.
For large enterprises, especially in government or defense, Noblis G3 offers superior accuracy (85.2%) for technical documentation. However, it demands heavy upfront investment. One Department of Defense contractor reported spending six months and three full-time engineers just to configure the knowledge base. Once set up, though, it reduced factual errors in reports by 57%.
The Hidden Costs: Latency, Money, and False Positives
Here’s the catch: verification isn’t free. Every time you check a claim, you burn compute cycles and API credits. Let’s look at the numbers.
Using a powerful verifier like GPT-4 yields high accuracy (78.4% on FactBench) but costs $0.042 per verification and takes 12.7 seconds per claim. For a long response with ten claims, that’s 127 seconds of latency and $0.42 in API costs per query. Multiply that by thousands of users, and the bill explodes.
A more cost-effective alternative is using smaller models like Llama-3-8B as verifiers. They drop accuracy slightly to 72.1% but cut costs to $0.008 per verification and drastically reduce latency. For most commercial applications, this trade-off is worth it. You don’t need perfect academic accuracy; you need "good enough" truth at a sustainable price.
Then there’s the issue of false positives. Systems incorrectly flagging correct information as wrong average an 18.7% false positive rate. This frustrates users when the AI refuses to state a known fact because it couldn’t find a direct source. To mitigate this, successful implementations use hybrid retrieval (BM25 + dense vectors), which reduces false negatives by 27%, and set confidence thresholds to ignore borderline cases.
Where Current Systems Still Fail
Even the best online verification strategies have blind spots. You need to know what these are so you don’t deploy a fragile system.
First, temporal knowledge is a nightmare. Systems show a 32.6% accuracy degradation on time-sensitive claims. If you ask, "Who is the current CEO of X?", and your knowledge base is six months old, the verifier will likely mark the correct answer as false because it matches outdated data. Keeping knowledge bases fresh is a full-time job.
Second, nuanced or counterfactual reasoning remains weak. Accuracy drops below 45% for counterfactual tasks (e.g., "If Napoleon had won Waterloo..."). These aren't factual errors in the traditional sense, but automated checkers struggle to distinguish between historical fiction and hallucinated history.
Third, cultural bias persists. Non-Western topics see a 41.3% lower accuracy rate because training data and knowledge sources are heavily skewed toward English and Western perspectives. If your app serves a global audience, you must audit your verification results for regional biases.
Implementation Guide: From Prototype to Production
Ready to add verification to your stack? Don’t just plug in an API. Follow this structured path to avoid common pitfalls.
- Setup and Configuration (4-6 hours): Start with a framework like OpenFactCheck or FactScore. Configure your evidence retriever. Do not rely solely on Wikipedia. Integrate your own domain-specific documents. Users report that configuring custom knowledge bases is the hardest part, often taking days due to poor documentation examples.
- Customization and Tuning (8-10 hours): Adjust your claim extraction prompts. Generic prompts miss subtle claims. Tune your confidence thresholds. If you set them too high, you’ll get false positives. Too low, and you’ll let hallucinations through. Test against a small, labeled dataset from your specific domain.
- Integration and Latency Management (3-4 hours): Decide when to verify. Verifying every single word kills performance. Instead, pre-filter likely factual content. Only trigger verification for sentences containing entities, dates, or statistics. Implement asynchronous verification where possible, showing the user the draft first and updating it if corrections are needed.
Expect a learning curve. Developers report needing 6-8 weeks to reach production-ready status. You’ll need intermediate NLP knowledge to understand claim extraction techniques and skills in vector database management to handle retrieval efficiently.
The Future: Self-Correcting Models
The industry is moving away from external checkers toward "self-correcting" paradigms. Newer models are trained to pause generation, verify their own high-risk claims internally, and refine the output before finishing the sentence. Early results from MIT studies show this self-verification reduces final output errors by an additional 22.4% beyond standard external checks.
By 2027, Gartner predicts 95% of enterprise LLM deployments will incorporate some form of factuality verification. The EU’s AI Act, effective February 2025, already mandates technical measures to mitigate factual risks in high-risk applications. If you’re building serious AI products, verification isn’t optional anymore-it’s compliance.
What is the difference between online and offline verification?
Offline verification checks the entire output after generation is complete, which is slower but allows for comprehensive analysis. Online verification intercepts and checks claims in real-time during generation, enabling immediate correction and reducing latency for the end-user, though it requires more complex architecture.
Can online verification eliminate all hallucinations?
No. While it reduces factual errors by 40-60%, it cannot eliminate them entirely. Systems struggle with nuanced context, temporal updates, and counterfactual reasoning. Human oversight remains necessary for high-stakes applications like law or medicine.
Which framework is best for startups?
FactScore is often recommended for startups due to its low latency and ease of integration. It offers a good balance of accuracy and speed without the heavy computational overhead of frameworks like OpenFactCheck, making it suitable for production environments with budget constraints.
How much does verification increase API costs?
It varies significantly. Using GPT-4 as a verifier can add $0.042 per claim, while smaller models like Llama-3-8B cost around $0.008. For high-volume applications, choosing a lightweight verifier is critical to maintaining profitability.
Do I need my own knowledge base?
Yes, for domain-specific applications. Relying solely on general web sources like Wikipedia leads to generic or outdated answers. Integrating your proprietary data ensures the verifier checks against the most relevant and accurate information for your specific use case.